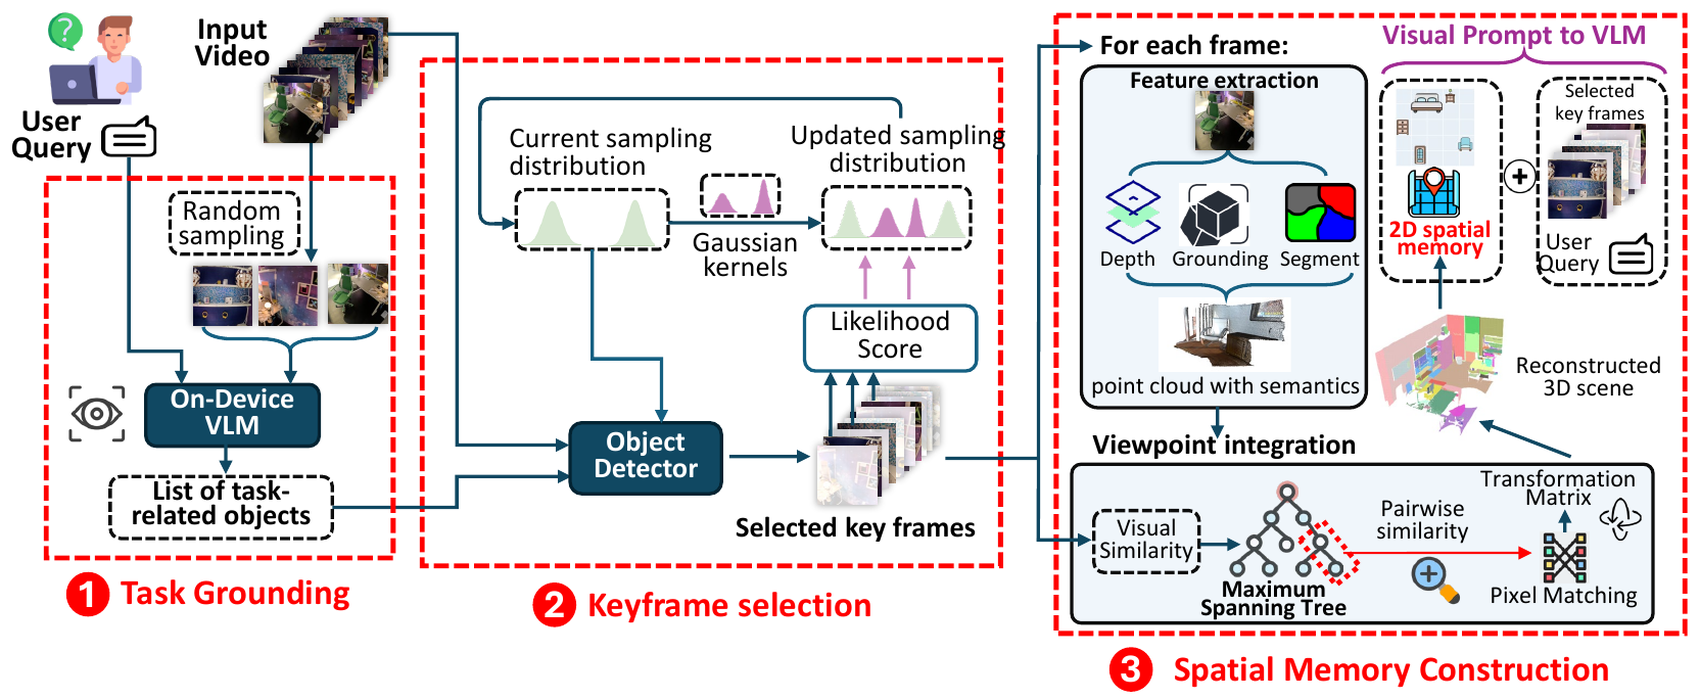
@inproceedings{wang2026spatialmind,title={SpatialMind: Spatially Aware On-Device Embodied AI via Viewpoint Integration},author={Wang, Haoming and Xue, Qiyao and Liu, Weichen and Yang, Boyuan and Yin, Xiangyu and Gao, Wei},booktitle={Proceedings of the Annual International Conference on Mobile Computing and Networking},year={2026},publisher={ACM},selected=true}
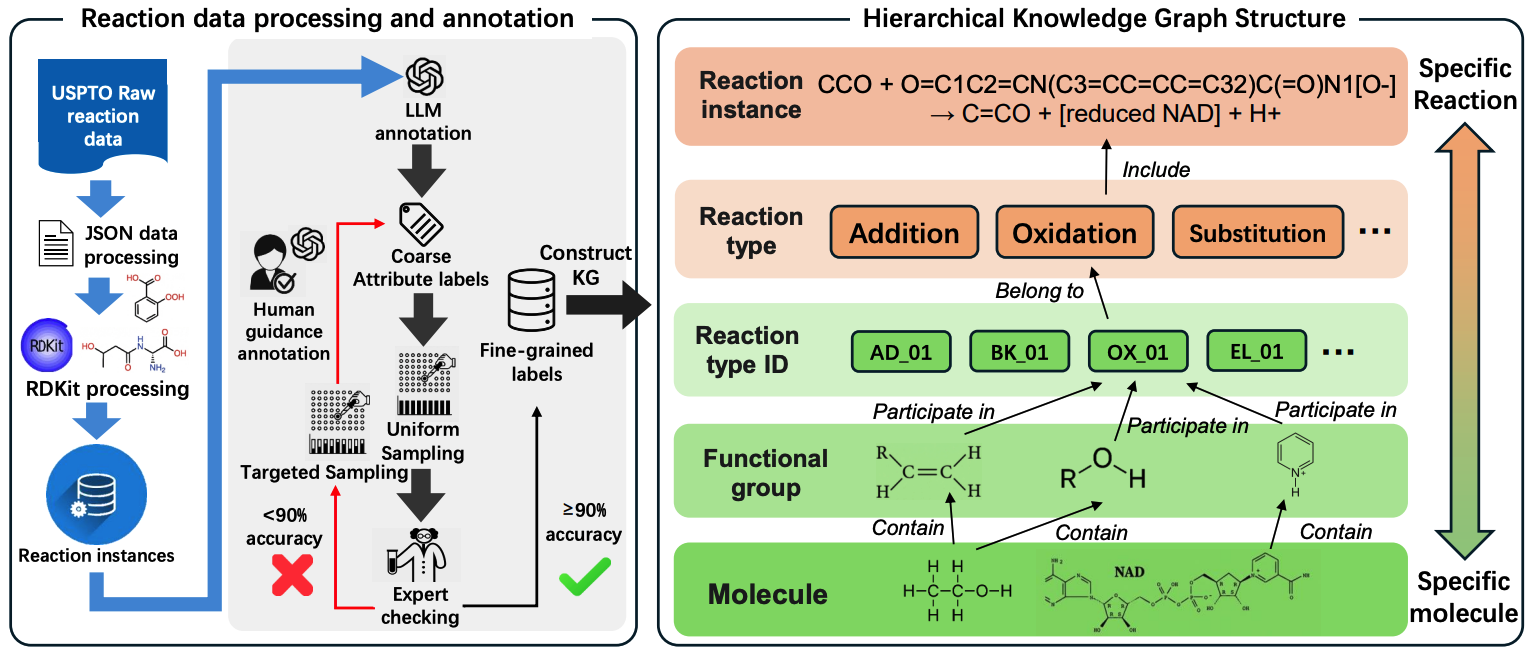
@inproceedings{liu2026kgrxn,title={KGRxn-LLM: Knowledge Graph Enhanced Large Language Models for Molecular Reaction Reasoning},author={Liu, Weichen and Xue, Qiyao and Wu, Yuyang and Isayev, Olexandr and Miskov-Zivanov, Natasa},booktitle={Proceedings of the Workshop on Biomedical Natural Language Processing (BioNLP)},year={2026},selected=true}
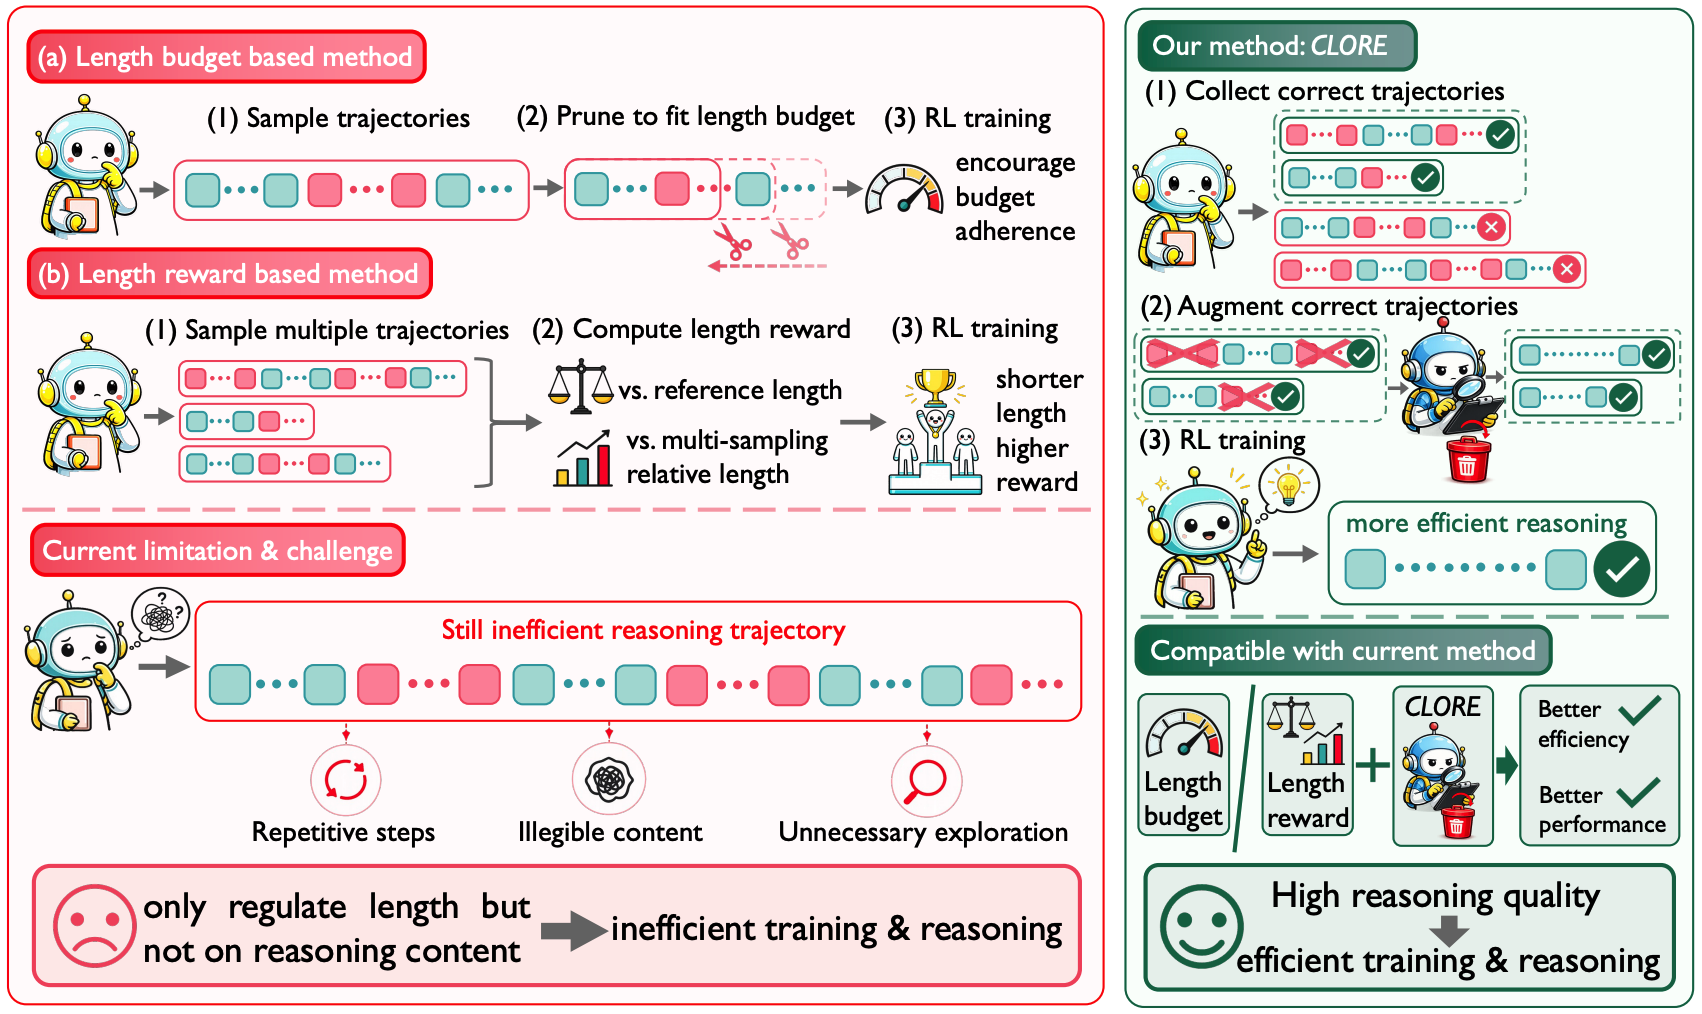
@article{wu2026clore,title={CLORE: Content-Level Optimization for Reasoning Efficiency},author={Wu, Yuyang and Xue, Qiyao and Lu, Guanxing and Liu, Weichen and Wang, Zihan and Li, Manling and Isayev, Olexandr},journal={arXiv preprint arXiv:2605.22211},year={2026},}
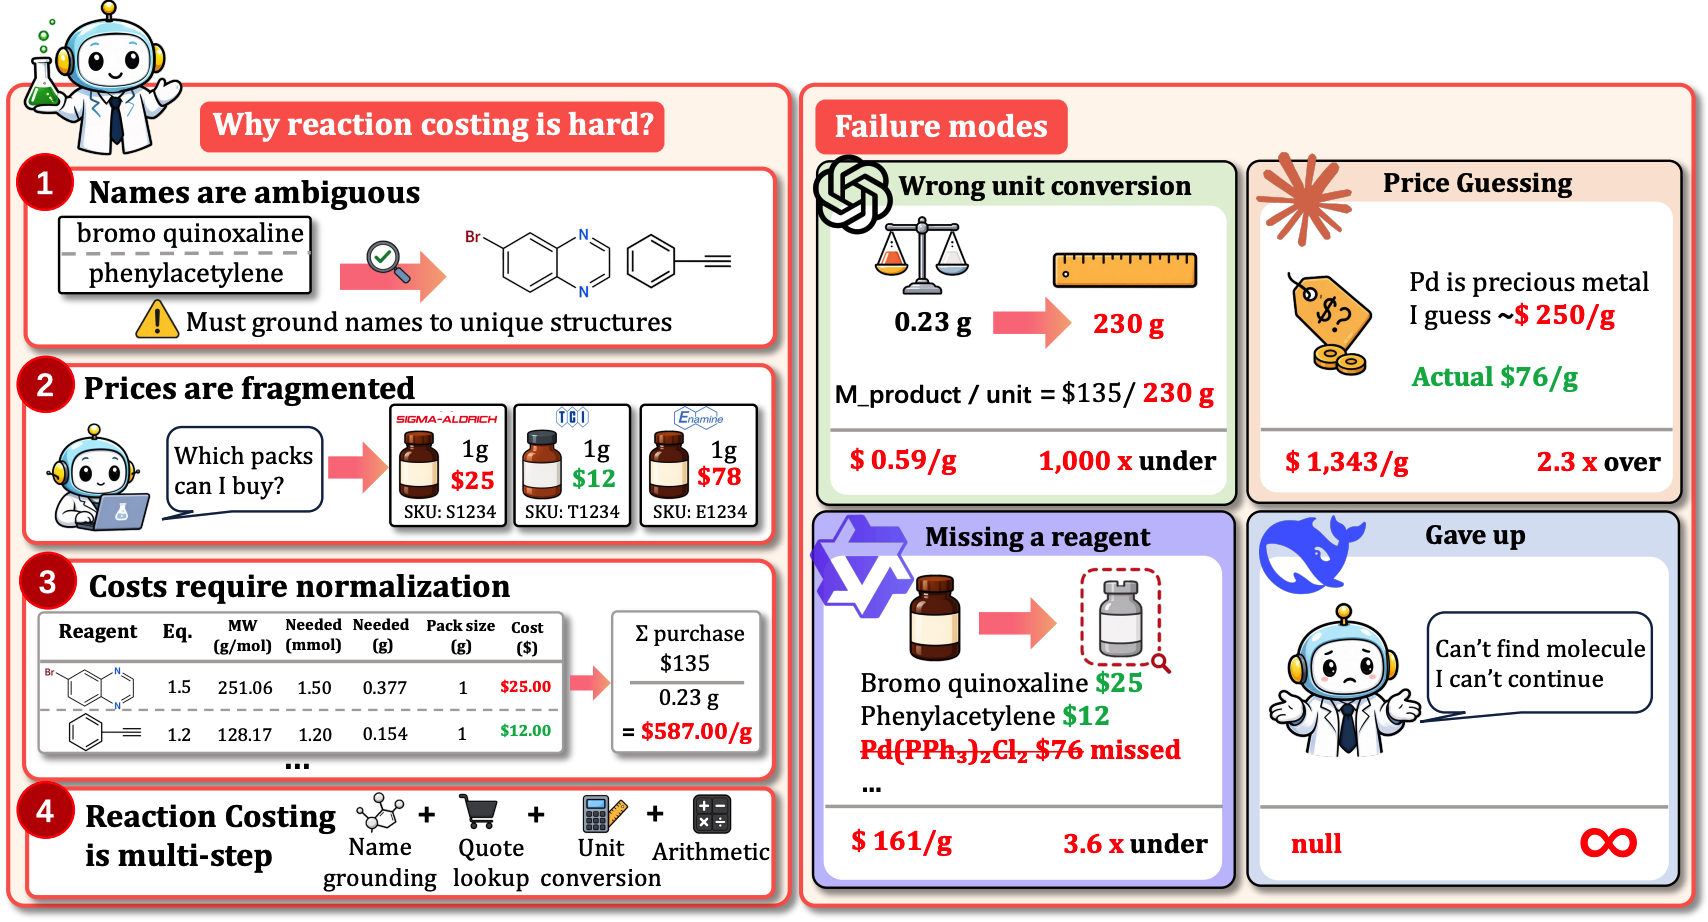
@article{wu2026price,title={Can Agents Price a Reaction? Evaluating LLMs on Chemical Cost Reasoning},author={Wu, Yuyang and Huang, Yue and Shen, Shuaike and Wang, Xujian and Zhang, Shuhao and Xue, Qiyao and Liu, Weichen and Gao, Runtian and Ma, Jian and Zhang, Xiangliang and Isayev, Olexandr},journal={arXiv preprint arXiv:2605.07251},year={2026},}
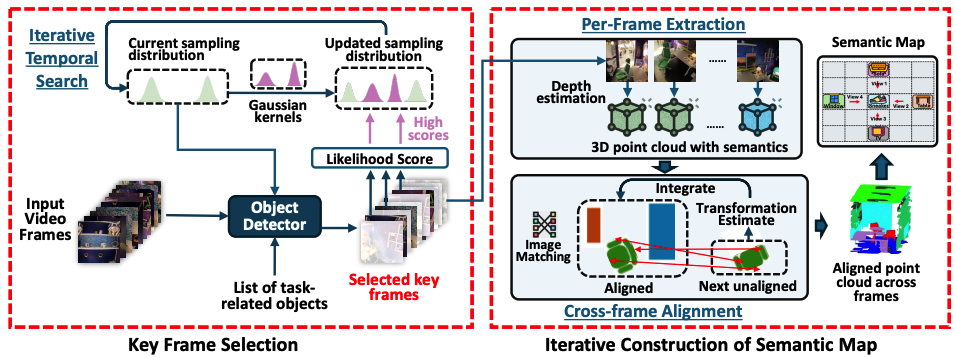
@article{wang2026mosaicthinker,title={MosaicThinker: On-Device Visual Spatial Reasoning for Embodied AI via Iterative Construction of Space Representation},author={Wang, Haoming and Xue, Qiyao and Liu, Weichen and Gao, Wei},journal={arXiv preprint arXiv:2602.07082},year={2026},}
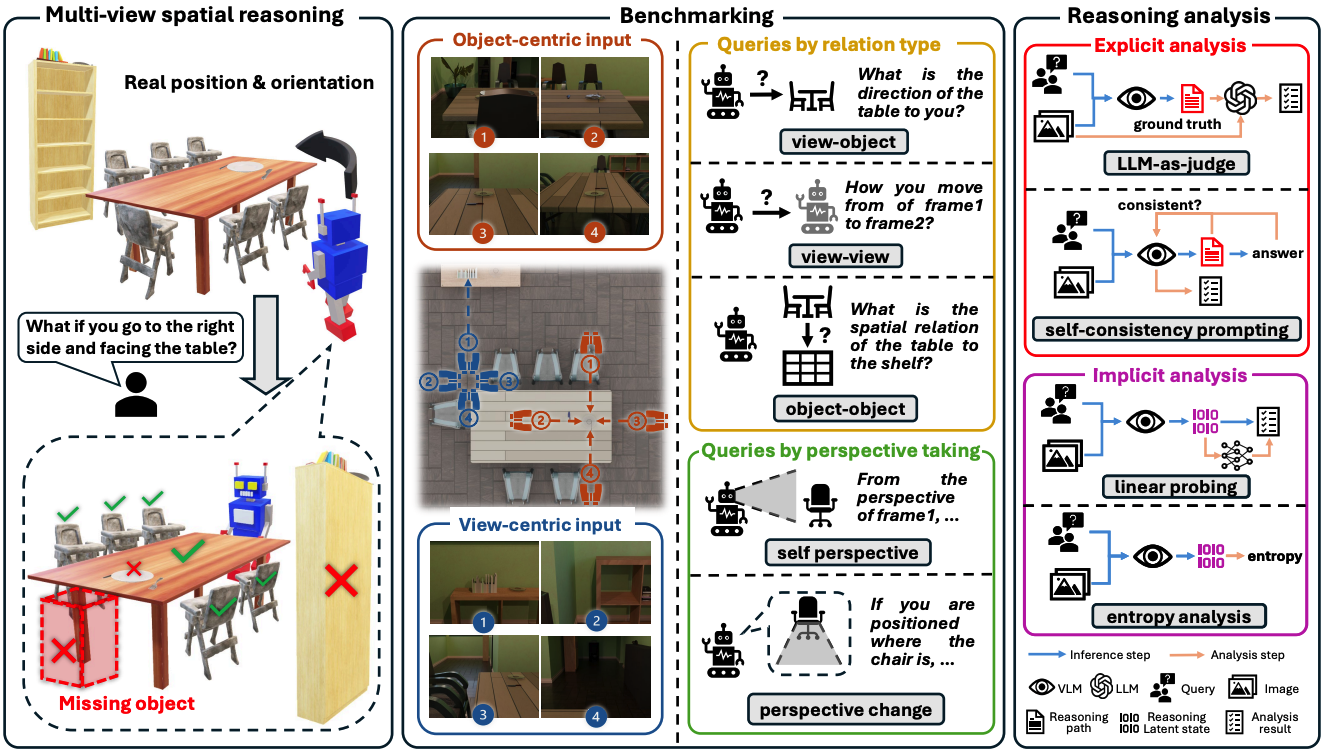
@inproceedings{xue2026reasoningpath,title={Reasoning Path and Latent State Analysis for Multi-view Visual Spatial Reasoning: A Cognitive Science Perspective},author={Xue, Qiyao and Liu, Weichen and Wang, Shiqi and Wang, Haoming and Wu, Yuyang and Gao, Wei},booktitle={Proceedings of the European Conference on Computer Vision},year={2026},selected=true}
@inproceedings{xue2026infinigen,title={InfiniBench: Infinite Benchmarking for Visual Spatial Reasoning with Customizable Scene Complexity},author={Wang, Haoming and Xue, Qiyao and Gao, Wei},booktitle={Proceedings of the Computer Vision and Pattern Recognition Conference},year={2026},doi={10.48550/arXiv.2511.18200},publisher={CVPR},selected=true}
AAAI
MMBERT: Scaled Mixture-of-Experts Multimodal BERT for Robust Chinese Hate Speech Detection under Cloaking Perturbations
Qiyao Xue, Yuchen Dou, Ryan Shi, and 2 more authors
In Annual AAAI Conference on Artificial Intelligence, 2026
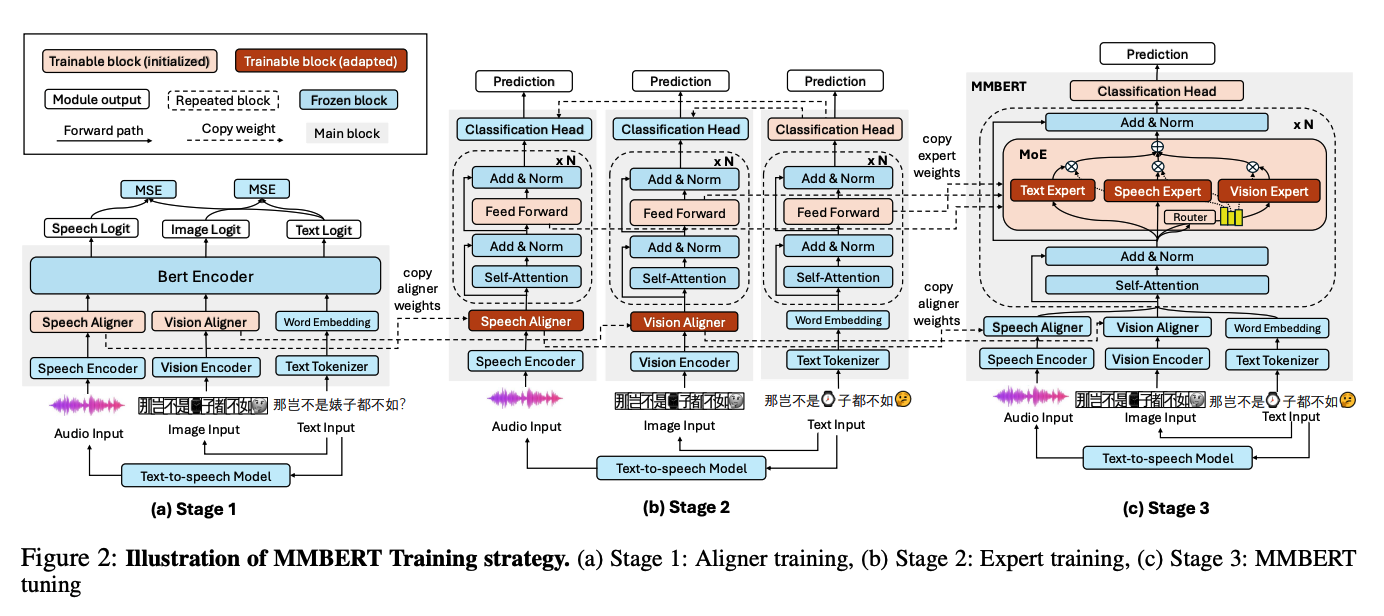
@inproceedings{xue2026mmbert,title={MMBERT: Scaled Mixture-of-Experts Multimodal BERT for Robust Chinese Hate Speech Detection under Cloaking Perturbations},author={Xue, Qiyao and Dou, Yuchen and Shi, Ryan and Li, Xiang Lorraine and Gao, Wei},booktitle={Annual AAAI Conference on Artificial Intelligence},year={2026},doi={10.48550/arXiv.2508.00760},publisher={AAAI},selected=true}
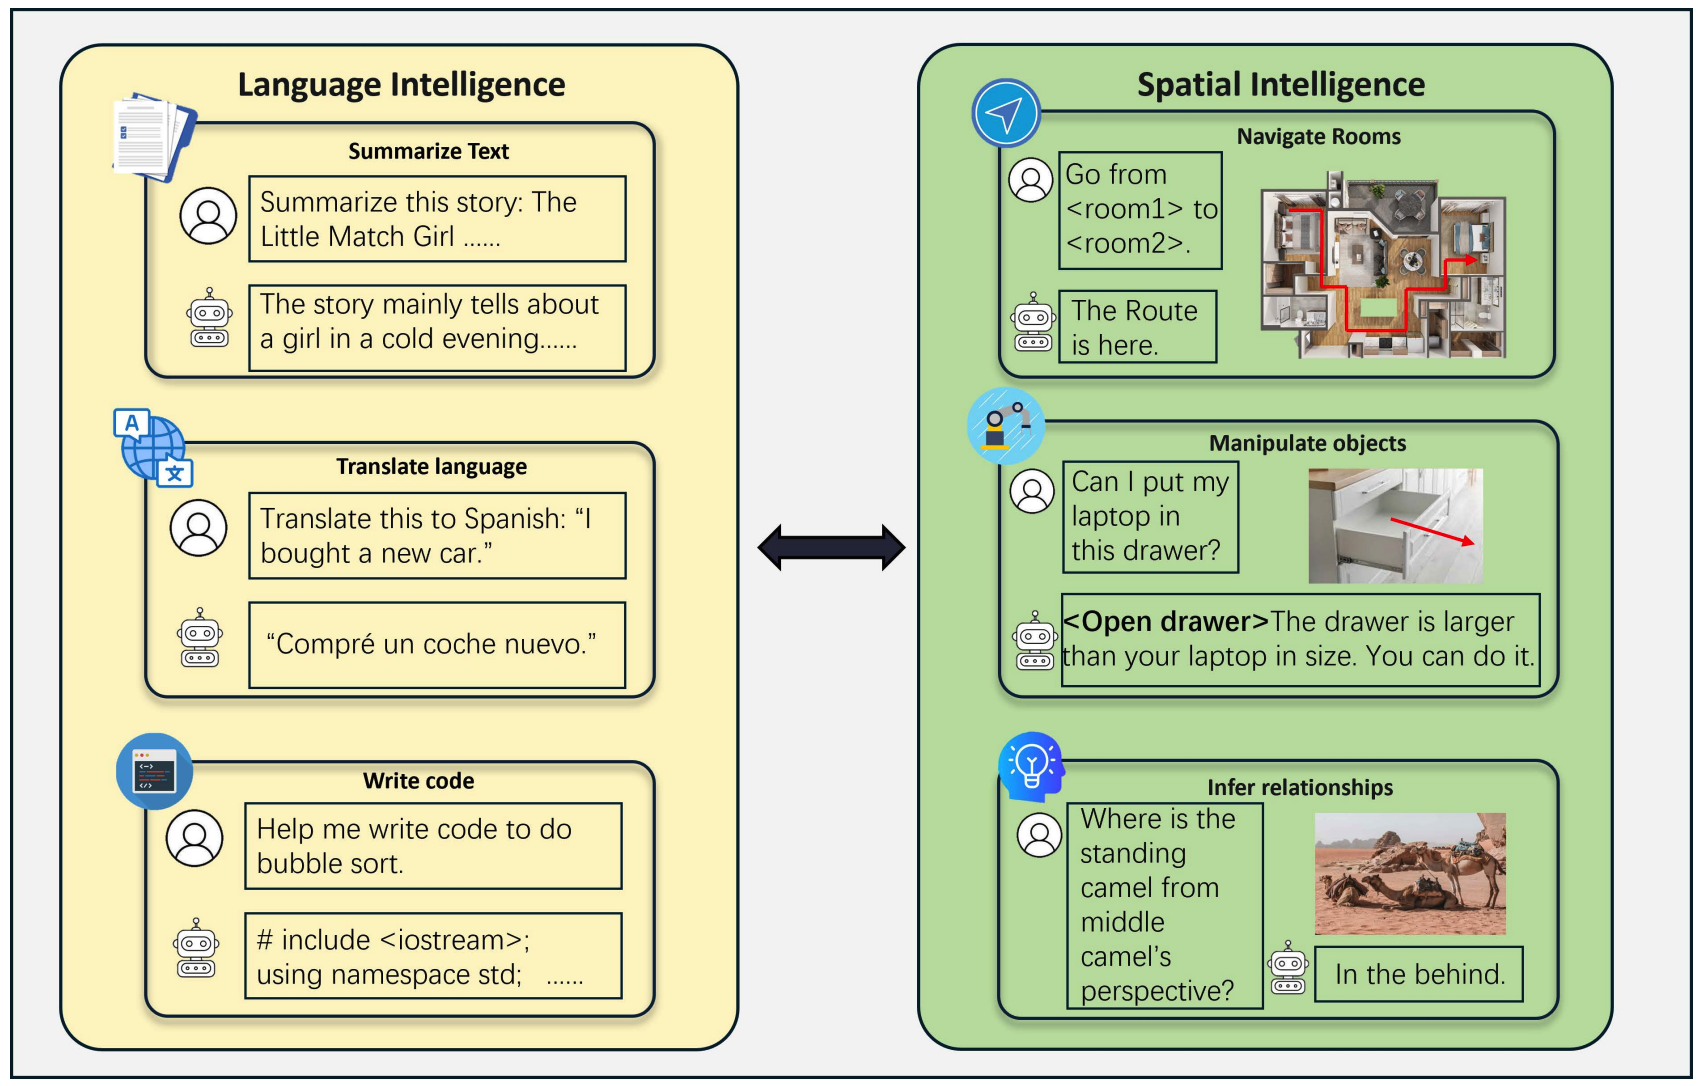
@article{liu2025spatialsurvey,title={Spatial Reasoning in Multimodal Large Language Models: A Survey of Tasks, Benchmarks and Methods},author={Liu, Weichen and Xue, Qiyao and Wang, Haoming and Yin, Xiangyu and Yang, Boyuan and Gao, Wei},journal={arXiv preprint arXiv:2511.15722},year={2025},}
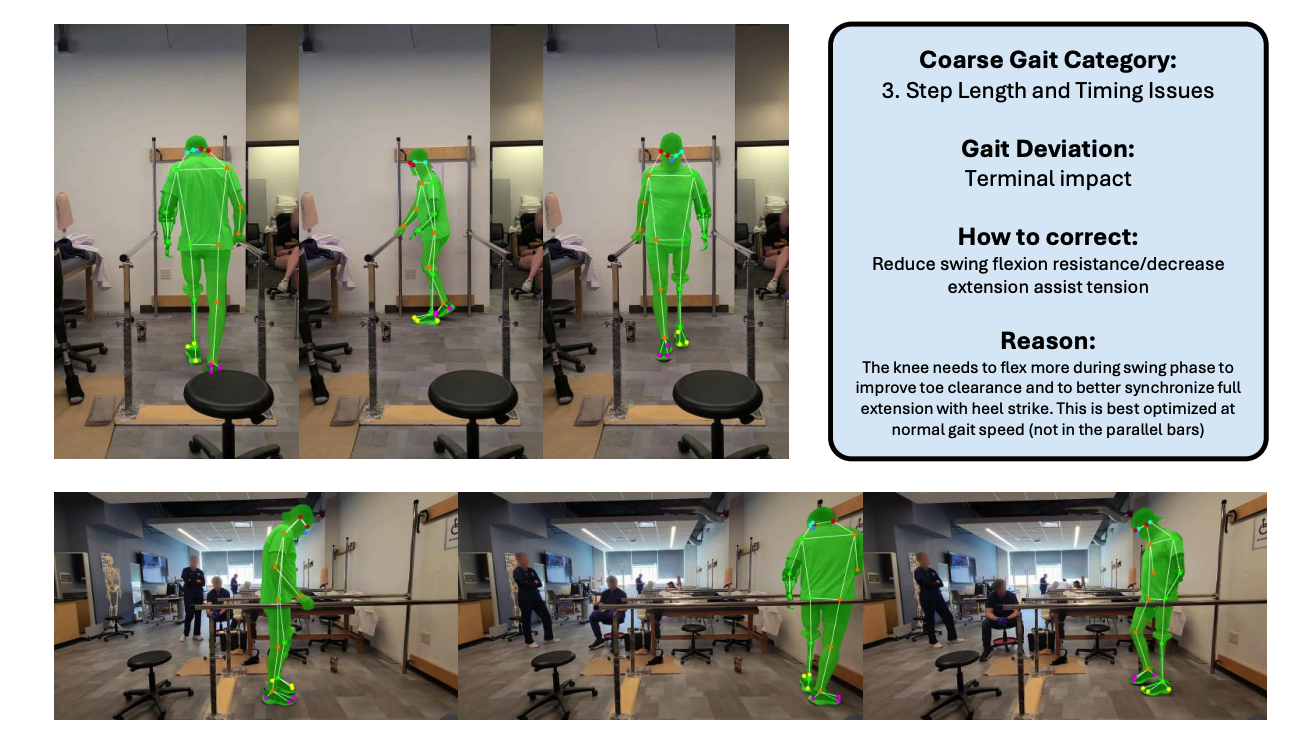
@inproceedings{yin2025progait,title={ProGait: A Multi-Purpose Video Dataset and Benchmark for Transfemoral Prosthesis Users},author={Yin, Xiangyu and Yang, Boyuan and Liu, Weichen and Xue, Qiyao and Alamri, Abrar and Fiedler, Goeran and Gao, Wei},booktitle={Proceedings of the International Conference on Computer Vision},year={2025},doi={10.48550/arXiv.2507.10223},publisher={ICCV},selected=true}
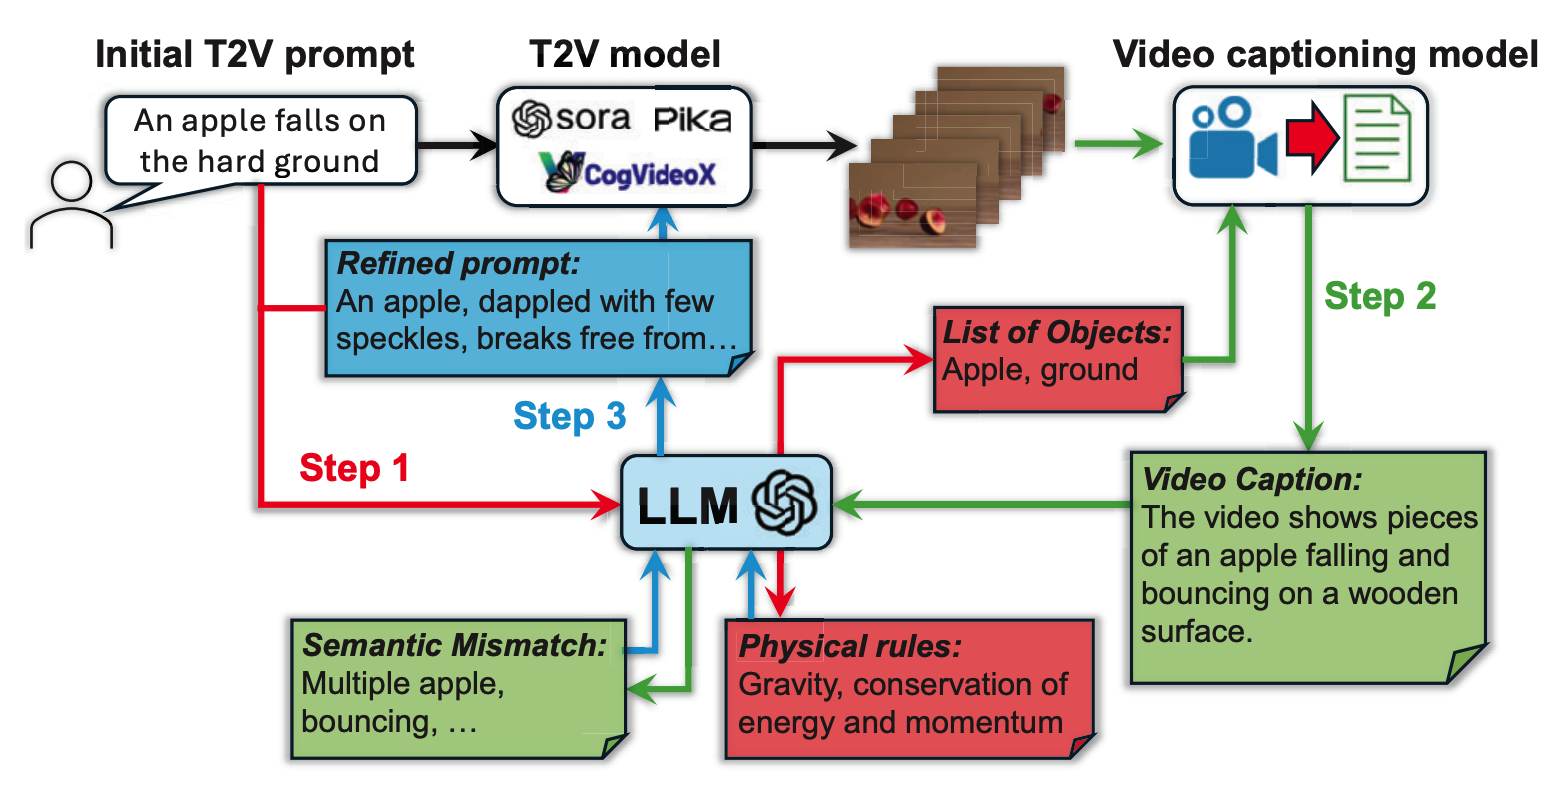
@inproceedings{xue2025phyt2v,title={Phyt2v: Llm-guided iterative self-refinement for physics-grounded text-to-video generation},author={Xue, Qiyao and Yin, Xiangyu and Yang, Boyuan and Gao, Wei},booktitle={Proceedings of the Computer Vision and Pattern Recognition Conference},pages={18826--18836},year={2025},doi={10.48550/arXiv.2412.00596},publisher={CVPR},selected=true}